
If you’ve spent any time building with Claude this year, you’ve probably noticed the shift. Teams aren’t asking “can Claude answer this question” anymore; they’re asking “can Claude run this workflow end to end, unattended, and tell us when something’s wrong.” That’s the gap Claude Certified Architect Foundations hands-on training is built to close, and it’s why Anthropic’s new architect-track exam has become the credential recruiters actually ask about in 2026.
This guide is not a definitions list. It’s a lab manual, full of Claude Certified Architect project examples you can build today. You’ll build a small multi-agent system, wire up a real MCP server, walk through a Claude Code workflow from a blank repo to a CI/CD pipeline, and deploy a production agent, all before you sit the exam. Along the way you’ll get the architecture patterns, the prompt techniques, and a curated set of repos worth forking, so that by the time you close this tab you have something in your portfolio, not just notes.
Why this matters right now
2026 is the year agentic AI stopped being a demo and started being infrastructure. Support desks, data pipelines, code review, and internal tooling are all being rebuilt around agents that plan, call tools, and hand off work to other agents. That shift created a real problem for hiring managers: anyone can say they’ve built AI agents. Very few can prove they understand the tradeoffs, when to use a workflow instead of an autonomous loop, how to scope a tool so two similar tools don’t collide, how to keep a long-running agent from quietly running out of context.
That’s exactly what Anthropic’s certification is designed to test, and it’s why treating the exam as a checklist to memorize is the wrong approach. The right approach is to build the systems the exam is modeled on. That’s what the four labs below do.
📥 Get Your Free Claude Certified Architect Hands-On Labs PDF
Only the 4 labs + GitHub repos + architecture patterns + roadmap. Colourful and ready to build.
Download Free Hands-On Labs PDF (20+ Pages)PassITExams – Your one-stop shop for AI certification mastery
Before you start: clone a starter repo, keep a scratch folder for the code samples in this guide, and have a Claude API key (or Claude Code) ready. Every lab here is designed to be built in an afternoon, not a weekend.
The credential is already influencing hiring and promotion decisions. For a clear look at the job titles, salary ranges, and long-term career path that follow the certification, see this analysis of the Claude Certified Architect Foundations career impact.
What Is the Claude Certified Architect Foundations Exam?
The Claude Certified Architect – Foundations exam, Anthropic’s own exam code is CCAR-F, though you’ll also see it written CCA-F, is the entry-level credential in Anthropic’s architect certification track. It validates that a practitioner can make sound architectural tradeoffs across four core technologies: the Claude API, the Claude Agent SDK, Claude Code, and MCP.
Here’s the format, as published in Anthropic’s exam guide:
| Detail | Value |
|---|---|
| Format | Proctored, closed-book, scenario-based |
| Length | 60 questions, 120 minutes |
| Delivery | Pearson VUE, online proctored or in-person at a test center |
| Passing score | 720 out of a scaled 1,000 |
| Cost | $125 USD per attempt |
| Validity | 12 months |
| Access | Currently gated to Claude Partner Network member organizations, registered with a company email |
Pricing and access details as of 2026; confirm on the official Anthropic certification page before registering.
If you are still deciding whether Foundations is the right level for you, or whether you should aim directly for the higher tier, this side-by-side comparison of Claude Certified Architect Foundations vs Professional will help you choose based on experience level and career goals.
The exam draws its scenarios from a bank of six recurring situations, things like a customer support escalation agent, a coordinator-and-subagents research pipeline, and Claude Code wired into CI/CD, and tests whether you’d make the right call inside each one. It’s not asking you to define “agentic loop.” It’s putting you inside a broken or ambiguous version of one and asking what you’d change.
That scenario-first design is why this is considered the gold standard for agentic architects right now: it’s genuinely hard to pass by memorizing documentation. You have to have built the thing at least once.
The exam is designed around realistic production scenarios rather than simple definitions. For a complete breakdown of the official exam format, registration process, domain weights, and passing score, see the full Claude Certified Architect Foundations exam guide.
The five domains you’re actually tested on
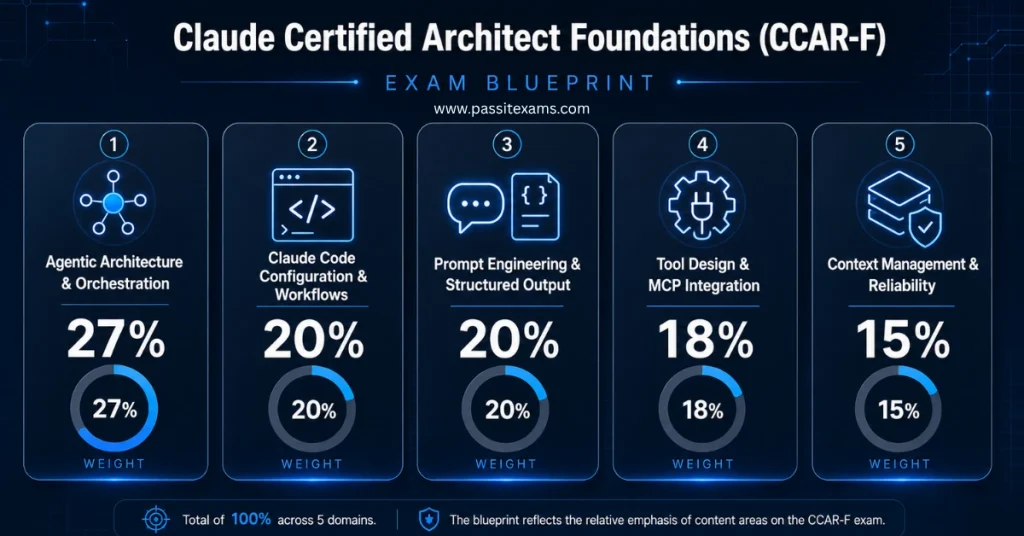
Per Anthropic’s published exam blueprint, the weighting looks like this:
- Agentic Architecture & Orchestration, 27%. The agentic loop, coordinator/subagent patterns, multi-agent topologies, task decomposition.
- Claude Code Configuration & Workflows, 20%. CLAUDE.md hierarchies, slash commands, hooks, plan mode, CI/CD integration.
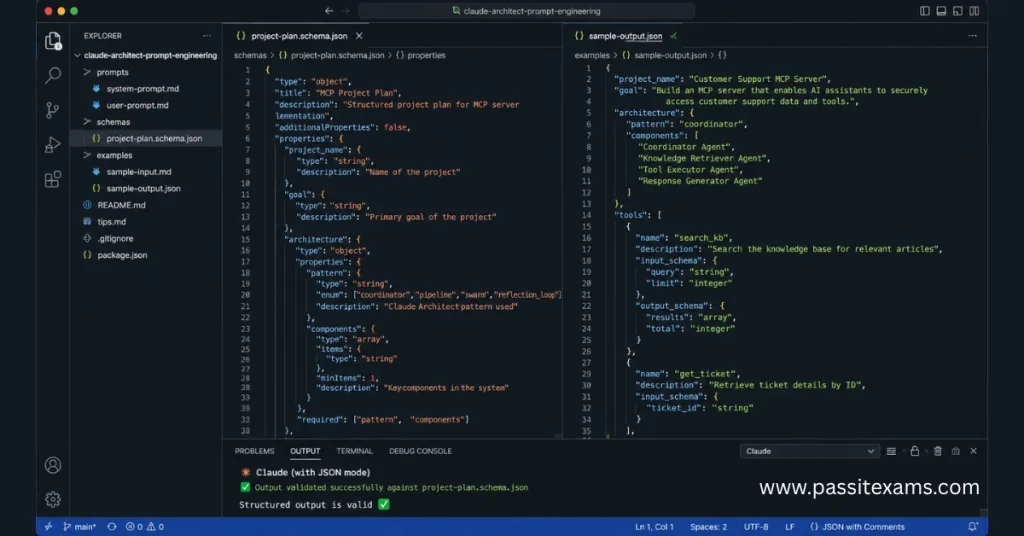
- Prompt Engineering & Structured Output, 20%. Explicit criteria, few-shot design, JSON schema enforcement, retry loops.
- Tool Design & MCP Integration, 18%. Tool descriptions, disambiguation, structured error responses, MCP server/client design.
- Context Management & Reliability, 15%. Context windows, prompt caching, failure handling, monitoring.
Notice that orchestration alone carries more weight than tool design and MCP integration combined. That should shape how you spend your study time, and it’s exactly why Lab 1, below, starts there.
Hands-On Lab 1: Building Your First Multi-Agent System
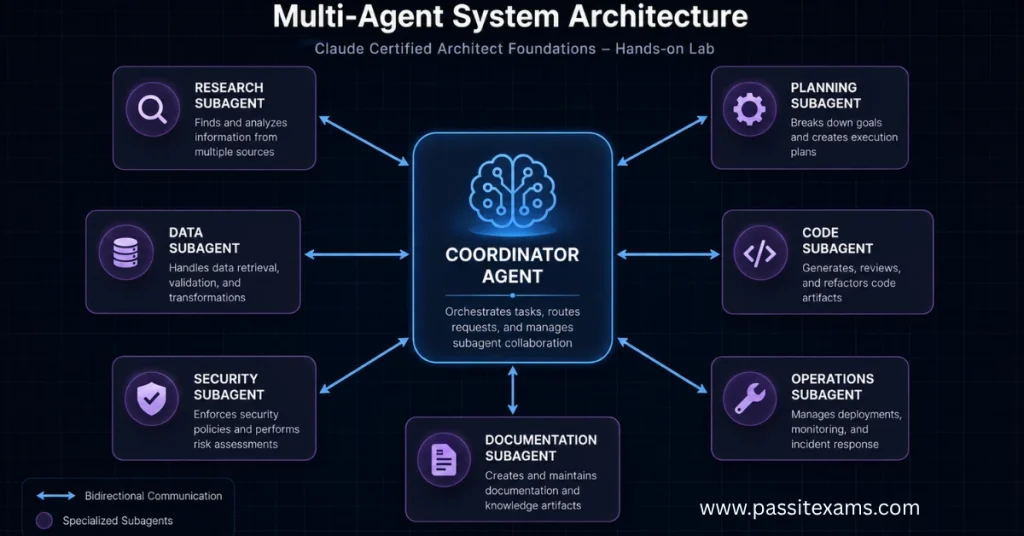
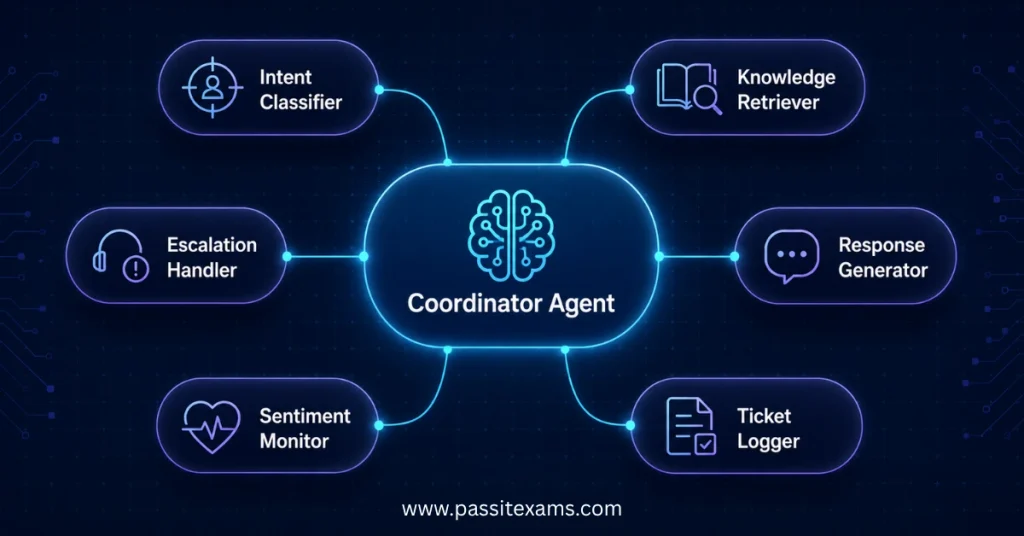
Scenario: a customer support escalation system. A single support agent that tries to do everything- read the ticket, check the order, decide on a refund, draft the reply- gets unreliable fast, because it’s juggling too many concerns in one context window. The architectural fix tested throughout Domain 1 is a multi-agent system Claude Architect pattern known as coordinator/subagent (hub-and-spoke): one orchestrator that reads intent and delegates, and narrowly-scoped subagents that each do one job well.
Step 1: Define the topology
                  ┌─────────────────────┐
                    │   Coordinator Agent   │
                    │  (reads ticket, plans,  │
                    │   delegates, merges)   │
                    └──────────┬────────────┘
              ┌─────────────────────┼───────────┐
              ▼                                                          ▼                              ▼
      ┌───────────────┐ ┌─────────────┐ ┌───────────────┐
                 Order Lookup                        Policy Check                     Reply Drafting
                    Subagent                                  Subagent                             Subagent
      └───────────────┘ └─────────────┘ └───────────────┘
Each subagent gets its own system prompt, its own scoped tools, and, critically, its own context window. That isolation is the whole point: the coordinator never has to reason about order-lookup logic, and the order-lookup agent never sees the customer’s raw complaint text.
Step 2: Set up the coordinator
from anthropic import Anthropic
client = Anthropic()
COORDINATOR_SYSTEM = """You are a support escalation coordinator.
Given a ticket, decide which specialist subagents to invoke and in what order.
Never resolve the ticket yourself, delegate, then synthesize the subagent results
into a final decision with a confidence score."""
def run_coordinator(ticket_text: str):
    response = client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=1024,
        system=COORDINATOR_SYSTEM,
        messages=[{"role": "user", "content": ticket_text}],
        tools=[order_lookup_tool, policy_check_tool, reply_draft_tool],
    )
    return response
Step 3: Scope each subagent tightly
A common exam trap, and a common production bug, is a subagent whose system prompt is too broad, so it starts making decisions that belong to another agent. Keep each one narrow:
ORDER_LOOKUP_SYSTEM = """You look up order details ONLY.
You never discuss refund eligibility or policy.
If asked about policy, respond: 'Not in scope for this agent.'"""
Step 4: Test the handoff, not just the happy path
The failure mode that actually breaks these systems isn’t the coordinator delegating correctly, it’s what happens when a subagent returns an ambiguous or partial result. Write your first tests around that:
def test_coordinator_handles_partial_subagent_result():
    partial_result = {"order_found": False, "reason": "customer_id_not_found"}
    decision = coordinator_synthesize(partial_result)
    assert decision["requires_human_review"] is True
That single test, does the system correctly escalate to a human instead of guessing, is close to the exact judgment the exam scores you on in Domain 1.
Why this scenario specifically: it’s one of the six official scenario categories the exam draws from, so building it isn’t just good practice, it’s rehearsing the real thing.
Hands-On Lab 2: Mastering Claude Code Workflows Tutorial
Domain 3, worth 20% of the exam, is entirely about whether you can configure Claude Code as a disciplined part of a team’s workflow, not just a chat window in your terminal. This is the Claude Code workflows tutorial most guides skip, because it’s less flashy than agent demos. It’s also where a lot of exam points live.
Step 1: Establish your CLAUDE.md hierarchy
Claude Code reads CLAUDE.md files hierarchically: repo root, then subdirectory, then user-level overrides. Put durable, project-wide rules at the root:
# CLAUDE.md (repo root)
## Conventions
- TypeScript strict mode, no implicit any
- Tests live next to source files as *.test.ts
- Commit format: type(scope): summary, no exceptions
## Before opening a PR
- Run `npm run lint && npm run test`
- Do not touch files under /legacy without explicit approval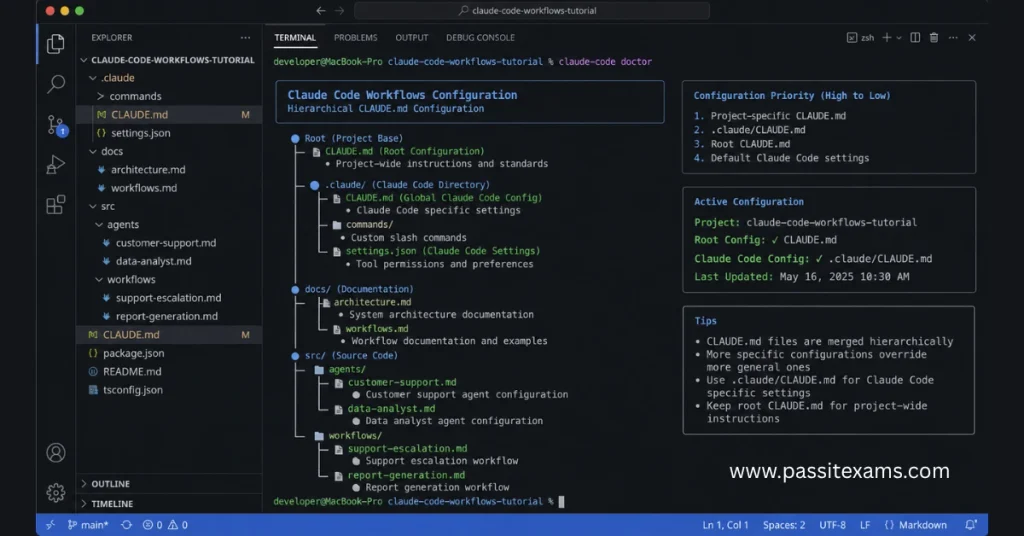
Step 2: Build a slash command for a repeatable task
If your team runs the same multi-step process often, say, “prep this PR for review”, encode it once:
# .claude/commands/prep-pr.md
Run the full lint and test suite. Summarize any failing tests.
Then draft a PR description using the conventional commit history
since the last merge to main. Flag any files over 400 lines changed
for manual review.
Step 3: Use plan mode before touching code
For anything non-trivial, ask Claude Code to plan before it edits:
> /plan Refactor the auth middleware to support both JWT and session cookiesPlan mode produces a reviewable checklist before a single file changes; this is the habit the exam expects you to default to, and it’s the difference between a fast agent and a reliable one.
Step 4: Wire it into CI/CD
# .github/workflows/claude-review.yml
name: Claude Code Review
on: [pull_request]
jobs:
  review:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Run Claude Code review
        run: |
          claude code review --diff origin/main...HEAD \
            --output-format json > review.json
      - name: Post review comment
        run: node scripts/post-review-comment.js review.json
That’s the full lifecycle: memory-file configuration → repeatable commands → plan-first editing → CI/CD. Every layer maps directly to a Domain 3 task statement.
Hands-On Lab 3: MCP Integration Claude Architect
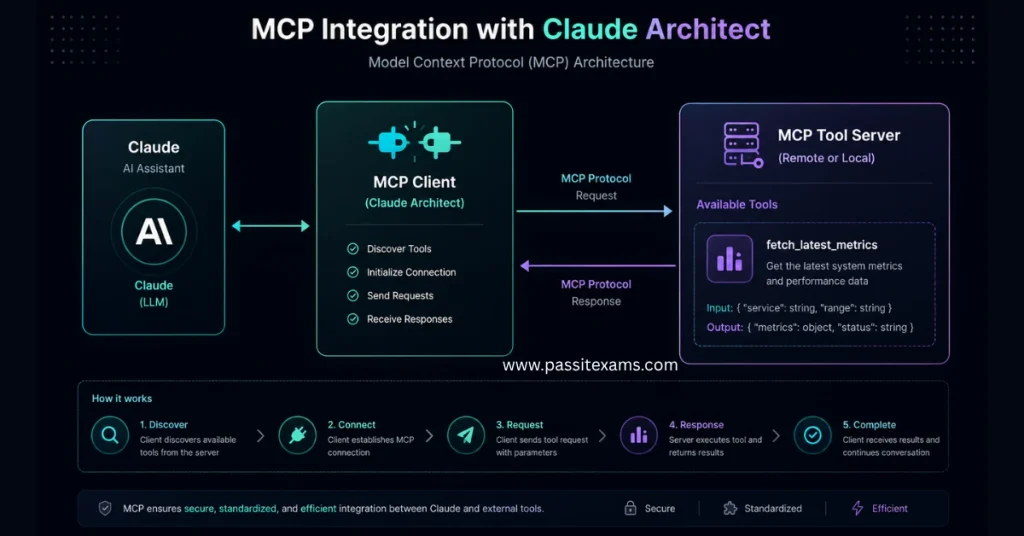
MCP integration Claude Architect work is worth 18% of the exam on its own, and it’s the domain most candidates underestimate, because MCP looks simple until you’re debugging why Claude keeps calling the wrong tool.
What MCP actually is
The Model Context Protocol is Anthropic’s open standard, released as open source, for connecting AI applications to external tools and data sources through a consistent client-server interface, instead of writing a bespoke integration for every API you want an agent to use. An MCP server exposes a set of tools (and optionally resources and prompts); any MCP-compatible client, including Claude Code and Claude Desktop, can discover and call them without custom glue code. Anthropic maintains reference server implementations, and SDKs now exist across TypeScript, Python, Java, C#, Go, and more, with contributions from partners including Microsoft, Google, and JetBrains.
Step 1: Build a minimal MCP server
from mcp.server import Server
from mcp.types import Tool, TextContent
app = Server("data-pipeline-agent")
@app.list_tools()
async def list_tools():
    return [
        Tool(
            name="fetch_latest_metrics",
            description=(
                "Fetch the latest hourly metrics snapshot for a given "
                "pipeline_id. Use this ONLY for real-time monitoring, "
                "for historical trends, use fetch_metrics_range instead."
            ),
            inputSchema={
                "type": "object",
                "properties": {
                    "pipeline_id": {"type": "string"}
                },
                "required": ["pipeline_id"],
            },
        )
    ]
@app.call_tool()
async def call_tool(name: str, arguments: dict):
    if name == "fetch_latest_metrics":
        data = query_metrics_store(arguments["pipeline_id"])
        return [TextContent(type="text", text=str(data))]
    raise ValueError(f"Unknown tool: {name}")
Notice the description explicitly disambiguates this tool from a similarly-named one (fetch_metrics_range). That’s not decoration; tool-description disambiguation is a named task statement in the exam’s Domain 2 blueprint, because it’s the single most common real-world cause of an agent calling the wrong tool. Getting this right is core to Claude Certified Architect tool integration work generally, not just this one lab.
Step 2: Return structured errors, not stack traces
@app.call_tool()
async def call_tool(name: str, arguments: dict):
    try:
        return [TextContent(type="text", text=str(query_metrics_store(arguments["pipeline_id"])))]
    except PipelineNotFoundError:
        return [TextContent(
            type="text",
            text='{"error": "pipeline_not_found", "recoverable": true, '
                 '"suggestion": "verify pipeline_id or list available pipelines"}'
        )]
A structured, recoverable error lets Claude reason about what to try next. A raw traceback just gets treated as “the tool failed”, and the agent gives up or hallucinates a workaround.
Step 3: Register the server with a client
{
  "mcpServers": {
    "data-pipeline-agent": {
      "command": "python",
      "args": ["-m", "data_pipeline_mcp_server"]
    }
  }
}
Project example, real-time data pipeline agent: connect the server above to a coordinator that polls fetch_latest_metrics every few minutes, compares against thresholds, and only escalates to a human (via a second MCP tool that posts to Slack) when a metric breaches its bound for two consecutive checks. That two-strike rule alone eliminates most alert-fatigue complaints, and it’s a pattern you’ll reuse constantly once you see it.
Hands-On Lab 4: Build Production AI Agents with Claude
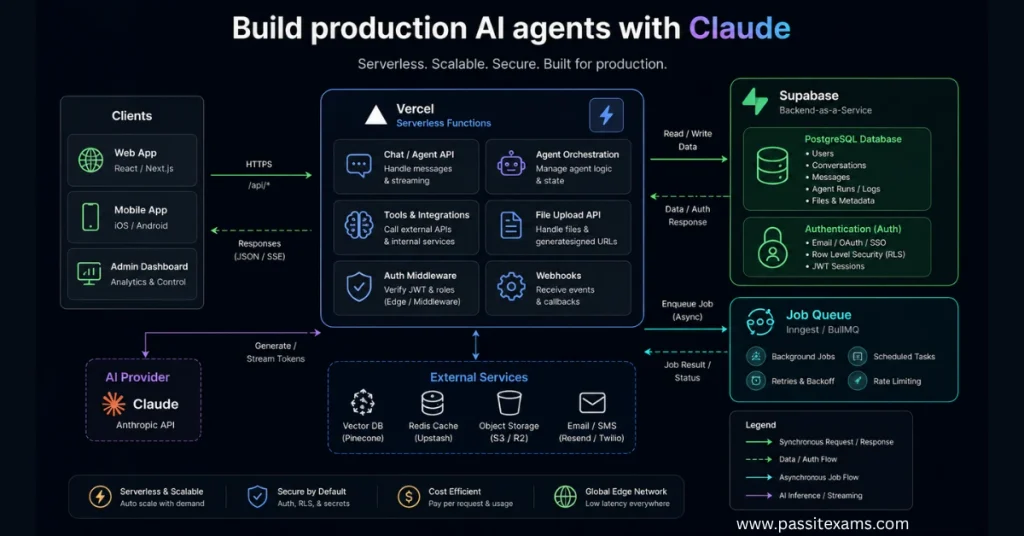
This is where the first three labs come together. To build production AI agents with Claude, you need three things a demo never has: error handling that doesn’t fail silently, monitoring you can actually act on, and a cost model you understand before the invoice arrives.
Step 1: Wrap every agent call with retry and backoff
import time
from anthropic import APIStatusError
def call_with_retry(client, **kwargs):
    max_attempts = 3
    for attempt in range(max_attempts):
        try:
            return client.messages.create(**kwargs)
        except APIStatusError as e:
            if e.status_code == 529 and attempt < max_attempts - 1:
                time.sleep(2 ** attempt)
                continue
            raise
Step 2: Log every tool call and decision point
Production agents fail in ways demos never reveal: a tool returns unexpected data, a subagent takes a wrong branch. Structured logs are the only way to debug after the fact:
import json, logging
def log_agent_step(step_type: str, payload: dict):
    logging.info(json.dumps({"step": step_type, **payload}))
log_agent_step("tool_call", {"tool": "fetch_latest_metrics", "pipeline_id": "p-104"})
log_agent_step("decision", {"agent": "coordinator", "action": "escalate", "confidence": 0.42})
Step 3: Control cost with prompt caching
For any agent that re-sends a large system prompt or tool schema on every turn, prompt caching is the single biggest lever you have:
response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=1024,
    system=[
        {"type": "text", "text": LARGE_SYSTEM_PROMPT, "cache_control": {"type": "ephemeral"}}
    ],
    messages=messages,
)
Step 4: Deploy on Vercel + Supabase
A minimal but genuinely production-viable stack for an agent backend:
- Supabase, Postgres for ticket/session state, plus row-level security so each customer only sees their own agent history.
- Vercel serverless functions, one endpoint that receives a webhook, invokes the coordinator, and writes results back to Supabase.
- A queue (Supabase’s built-in pg_cron or a lightweight external queue), so long-running agent tasks don’t block the HTTP response.
// api/agent-webhook.js (Vercel serverless function)
export default async function handler(req, res) {
  const { ticketId } = req.body;
  await supabase.from('agent_jobs').insert({ ticket_id: ticketId, status: 'queued' });
  res.status(202).json({ status: 'queued' });
}
That queue-and-respond-fast pattern matters more than it looks: it’s the difference between an agent that times out under load and one that scales.
Claude Certified Architect GitHub Repos: Must-Fork Projects
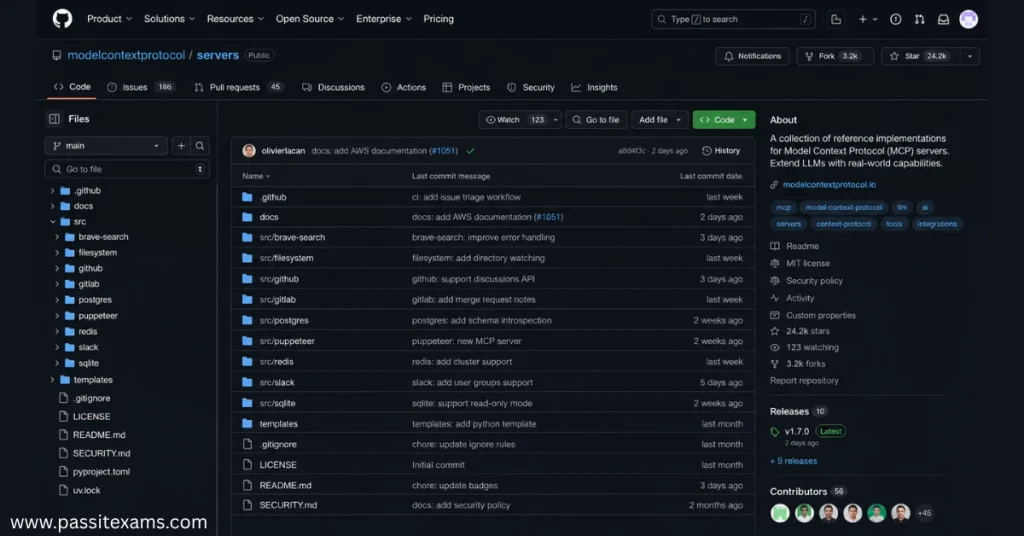
You don’t need to build every lab above from a blank file. These Claude Certified Architect GitHub repos are real, actively maintained, and worth forking as a starting point, listed here without invented star counts, because those numbers change weekly and you should just check them yourself:
- modelcontextprotocol/servers, Anthropic’s official collection of reference MCP servers (filesystem, Git, GitHub, Postgres, and more). The single best place to see idiomatic tool descriptions and error handling.
- modelcontextprotocol/modelcontextprotocol, the protocol specification itself. Worth reading directly rather than only through third-party summaries.
- modelcontextprotocol/inspector, a debugging tool for MCP servers; invaluable while building Lab 3.
- paullarionov/claude-certified-architect, a community-maintained study repo built specifically around the Foundations exam blueprint, with practical exercises across all five domains, plus translations including a Spanish-language track.
- Anthropic Cookbook (search “anthropic-cookbook” on GitHub), Anthropic’s own collection of API usage patterns, including multi-agent and tool-use examples.
Bonus: how to contribute and get visibility. The MCP servers repo explicitly welcomes community-contributed servers; start with a small, well-scoped server for a niche API you actually use, write a genuinely disambiguating tool description (see Lab 3), and open a PR. Reviewed contributions to a repo with this much traffic are one of the highest-leverage portfolio moves available to you right now.
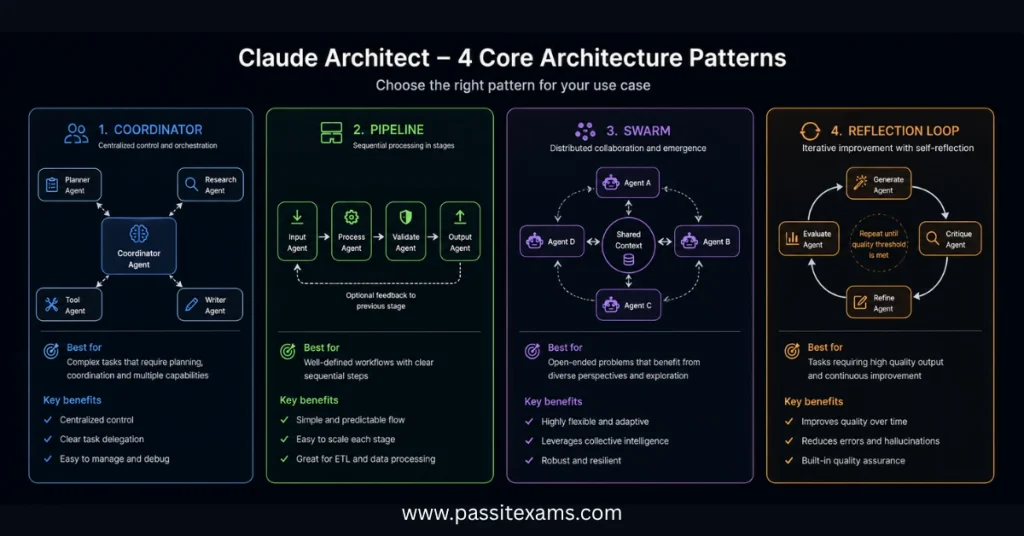
Claude Architect Architecture Patterns
Eight patterns worth having internalized before exam day, and before your next production design review. These Claude Architect architecture patterns cover the majority of real-world agent designs you’ll encounter:
| Pattern | Best for | Watch out for |
|---|---|---|
| Coordinator/Subagent (hub-and-spoke) | Distinct subtasks needing isolated context | Coordinator overload if subagents return too much raw data |
| Pipeline | Strict sequential stages (extract → transform → validate) | A single stuck stage blocks everything downstream |
| Peer-to-peer | Agents negotiating or cross-checking each other | Harder to debug; avoid unless you need it |
| Supervisor with veto | High-risk actions needing a gate before execution | Don’t let the supervisor become a second coordinator by accident |
| Swarm / parallel fan-out | Independent subtasks that can run concurrently | Rate limits and cost multiply fast, cap concurrency |
| Workflow (non-agentic) | Deterministic steps with no real branching | Teams reach for agents here when a simple script would do |
| Reflection loop | Output quality matters more than speed | Can loop forever without a max-iteration guard |
| Retrieval-augmented agent | Grounding responses in a private knowledge base | Stale or poorly-chunked retrieval silently degrades output |
A simple code template for the reflection-loop pattern, since it’s the one most often built wrong (no exit condition):
def reflect_and_revise(client, draft: str, criteria: str, max_loops: int = 2):
    for i in range(max_loops):
        review = client.messages.create(
            model="claude-sonnet-4-6",
            max_tokens=512,
            messages=[{"role": "user", "content": f"Criteria: {criteria}\n\nDraft:\n{draft}\n\nDoes this meet all criteria? Reply PASS or list issues."}],
        )
        if "PASS" in review.content[0].text:
            return draft
        draft = revise(client, draft, review.content[0].text)
    return draft  # return best-effort after max_loops, don't loop forever
If you remember one thing about Claude Architect architecture patterns for the exam: the correct answer is almost never “add more autonomy.” It’s usually “add the smallest amount of structure that fixes the specific failure mode in front of you.”
Prompt Engineering for Claude Architect Exam Success
Domain 4 is worth 20%, tied for the second-highest weight on the exam, and it rewards precision over cleverness. A few Prompt engineering for Claude Architect exam techniques that carry real exam weight:
1. Explicit success criteria beat vague instructions:
Bad:  "Summarize this ticket well."
Good: "Summarize this ticket in 2-3 sentences. Include: customer's core
       issue, any prior resolution attempts mentioned, and urgency level
       (low/medium/high) based on explicit language in the ticket."
2. Few-shot examples for structured output are worth more than long instructions: One well-chosen example of the exact JSON shape you want typically outperforms three paragraphs describing the shape.
3. Enforce schema, then validate outside the model:
import json
from jsonschema import validate
SCHEMA = {
    "type": "object",
    "properties": {
        "escalate": {"type": "boolean"},
        "confidence": {"type": "number", "minimum": 0, "maximum": 1},
    },
    "required": ["escalate", "confidence"],
}
def get_structured_decision(client, prompt: str):
    response = client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=256,
        messages=[{"role": "user", "content": prompt + "\n\nRespond ONLY with valid JSON matching this shape: {\"escalate\": bool, \"confidence\": float}"}],
    )
    parsed = json.loads(response.content[0].text)
    validate(instance=parsed, schema=SCHEMA)
    return parsed
4. Build a retry loop for invalid output, not just API failures: Structured-output validation failures are common enough that the exam treats “what do you do when the model returns malformed JSON” as its own decision point; the answer is a targeted re-prompt with the specific validation error, not a full restart.
5. Know the difference between a system prompt constraint and a user-turn instruction and use the right one: system-level rules for things that must never change mid-conversation, user-turn instructions for task-specific detail.
For exam-day strategy specifically: since four of the six official scenarios appear on every form, practicing against all six, not just your favorites, is the highest-leverage use of your remaining study time.
Real-World Scenarios for Claude Architect Labs
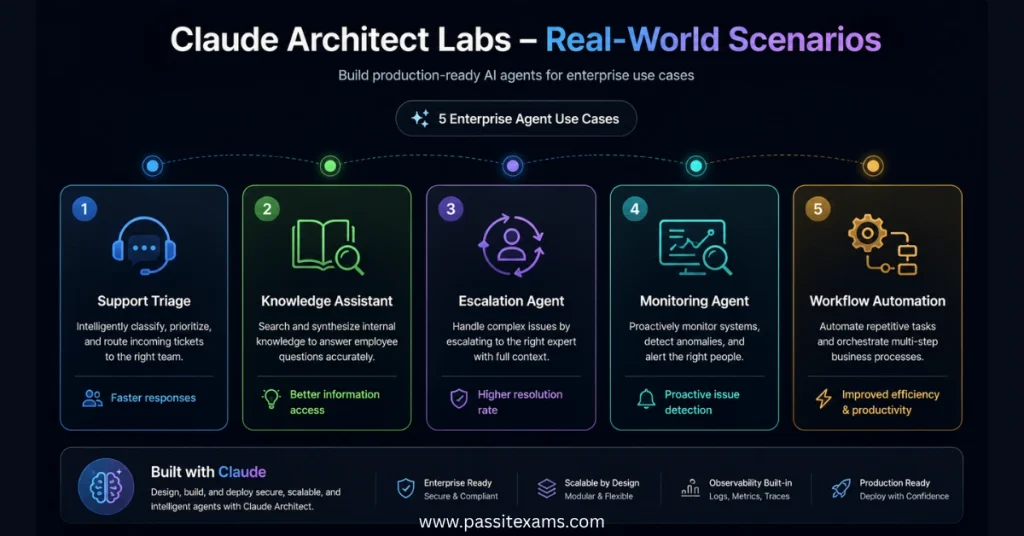
Five patterns worth adapting into your own portfolio, Claude Architect labs real-world scenarios framed as the kind of situations these systems get built for, rather than as specific case studies:
- Support ticket triage at scale. Coordinator classifies intent, subagents check order/account data, and a supervisor pattern gates any refund over a threshold for human approval. Mirrors the exam’s flagship scenario directly.
- Codebase research agent. A coordinator-subagent pair that explores an unfamiliar repo, using built-in file tools plus an MCP server for issue-tracker context, and produces a cited summary of how a feature works before a developer touches it.
- CI/CD review agent. Claude Code wired into pull-request workflows (as in Lab 2), generating structured review comments and flagging, never auto-merging, anything touching security-sensitive paths.
- Multi-source research pipeline. A coordinator that fans out to parallel subagents across different data sources, then a reflection-loop pattern (from the architecture patterns table) to check the synthesized report against the original sources before it’s shown to a human.
- Real-time monitoring agent. The data-pipeline pattern from Lab 3, extended with the two-strike escalation rule, adapted to whatever metrics your own team actually tracks.
Build even one of these fully, with tests, logging, and a deploy, and you’ll walk into the exam having already made most of the tradeoff decisions it’s going to ask you about.
If you prefer structured video training in addition to these hands-on labs, compare the best current Claude Certified Architect Foundations course options available in 2026.
Conclusion: Your 3-Month Roadmap
- Weeks 1–4: Build Labs 1 and 2. Get comfortable with the coordinator/subagent pattern and a real CLAUDE.md-driven workflow.
- Weeks 5–8: Build Labs 3 and 4. Ship one small MCP server to a public repo. Deploy the production agent stack, even if it’s just for yourself.
- Weeks 9–10: Study the architecture patterns table and the prompt-engineering techniques above until you can explain the tradeoffs out loud, not just recognize them on a page.
- Weeks 11–12: Take timed practice scenarios covering all six official categories. Register for the exam once you’re consistently scoring above the 720/1000 pass bar on practice material.
That’s a realistic, unrushed path from zero to exam-ready, and by the end of it, you won’t just have a certification. You’ll have a working multi-agent system, an MCP server, and a deployed production agent sitting in your GitHub profile, which is worth more to most hiring managers than the exam score itself.
If you want to go deeper on any single piece of this stack, see our companion guide to Claude Code configuration and CI/CD workflows for a longer walkthrough of Lab 2, and our MCP server design patterns post for more on the tool-disambiguation techniques from Lab 3.
Clone any project above and comment which one you built first; I read every comment and will help you debug.
Frequently Asked Questions FAQ’s
How do I pass the Claude Architect exam?
Build the systems the exam is modeled on (the labs above cover four of the six official scenarios), study the domain weights so you allocate time proportionally, and run timed practice scenarios before you register. Our exam-day strategy checklist covers pacing and distractor-spotting in more depth.
What is MCP in Claude Architect terms?
The Model Context Protocol is Anthropic’s open standard for connecting AI applications to external tools and data through a consistent client-server interface, removing the need for a custom integration per API.
Is Claude Certified Architect worth it in 2026?
For engineers actively building agentic systems, it’s a scenario-based, proctored credential, harder to pass by memorization than most AI certifications, which is precisely what makes it a stronger signal to employers.
How much does the CCAR-F exam cost?
$125 USD per attempt, per Anthropic’s published exam guide.
How long is the exam and how is it scored?
60 questions in 120 minutes, scored on a scale to 1,000 with a passing score of 720.
Who can register for the exam right now?
Access is currently gated to Claude Partner Network member organizations, and registration requires a verified company email address.
How is the exam delivered?
Via Pearson VUE, either online proctored from your own machine or in person at a Pearson VUE test center. Confirm current delivery options on Anthropic’s official certification page before booking, since logistics can change.
What’s the difference between CCA-F and CCAR-F?
They’re the same certification; CCA-F is the shorthand commonly used in the community, while CCAR-F is Anthropic’s official exam code.
Do I need a lower-level certification before Architect Foundations?
No. There’s no prerequisite certification, though Anthropic recommends roughly six or more months of hands-on experience with the Claude API, Agent SDK, Claude Code, and MCP.
Which exam domain should I study first?
Agentic Architecture & Orchestration, since it carries the highest weight at 27%; Lab 1 in this guide is built specifically around that domain.
Is there a free way to prepare for the exam?
Yes, freeCodeCamp published a full free video course covering all five exam domains on its YouTube channel, and Anthropic Academy offers free courses on Claude fundamentals, Claude Code, and cloud-platform integrations.
How long does the exam certification stay valid?
12 months from the date you pass, per Anthropic’s published policy. Confirm current details on Anthropic’s official certification page before you register, since program details can change.
